Malini ZhevqemiLeadership review 2026

Leadership review

Malini Zhevqemi

Chief Data Officer · India

Keep the work visible inside the number

Open to
  • Board appointments
  • Advisory roles
  • Speaking invitations
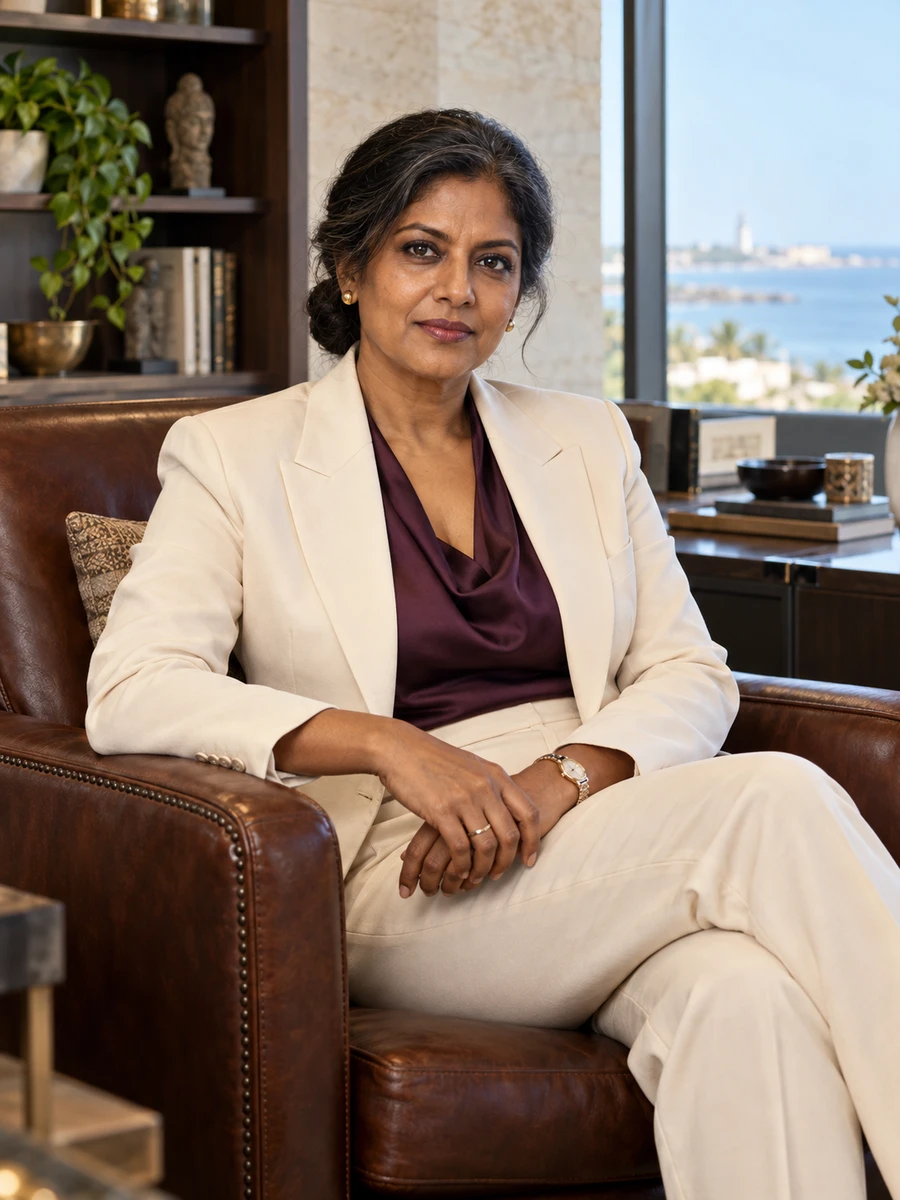
Portrait of Malini Zhevqemi

Keep the work visible inside the number

I lead data at Renvqathi Transit Containers in Puducherry, with production in Cuddalore. We make reusable polymer totes for non-food industrial components. The 550-person enterprise recorded ₹228 crore revenue and ₹18.8 crore operating profit for FY ending March 2026. Twenty-six data colleagues work through four leads within ₹6.9 crore annual expense. My role is to make evidence useful to decision-makers while preserving their authority over operations, financial reporting and product acceptance.

I am interested in what disappears when an operation becomes a summary. Two regional percentages can hide unequal populations. Returned products can reveal something important without representing everything shipped. A correct forecast total can conceal the wrong mix. A model can appear accurate because it overlooks the uncommon work it was intended to identify. I want the summary to remain connected to the question management actually needs to answer.

In 2019 I approved a combined review rate of 70%, averaging a 90% completeness result from 100 order-review records and a 50% result from 900 records. Under the same criterion, the pooled result was 540 of 1,000, or 54%. The sixteen-percentage-point correction was not a deterioration over time. It was a correction to my aggregation. Repairing the report cost ₹19 lakh, and I kept my approval responsibility in the explanation.

The returned population could not describe every tote shipped

Sixty-three of 180 returned totes showed hinge wear, or 35% of returns. The 35,000 shipment count did not provide a matched exposure cohort either. We retained the return finding and funded ₹52 lakh of follow-up data work without presenting it as a population failure rate or a proven technical cause.

A correct total concealed two opposing forecast errors

Two families had actual quantities of 1,200 and 800 against forecasts of 1,600 and 400. Both totals were 2,000, yet absolute family errors summed to 800, or 40% of actual quantity on that defined basis. The total alone could not describe the planning problem.

The model's impressive accuracy missed every uncommon case

A predeployment review contained 5,000 orders, including forty requiring special documentation. A candidate labelled all orders routine and scored 99.2% accuracy while missing all forty. We held the model and incurred ₹44 lakh in assessment and rework; no live customer harm is claimed.

Current focus

Connecting business summaries with their actual populations and intended decisions, including paired measures of a complete job rather than convenient sums of stage statistics. The next step should help colleagues act on the evidence, not merely tell them their preferred number is incomplete.

Conversations I welcome

A first outside board opportunity where data judgement can complement the institution's operating and financial expertise. I hold 2% within employee ownership and have no statutory appointment. Fictional IICA registration is complete but assessment remains unfinished; twenty-four provisional days require review against the actual role and my executive commitments.

Highlights

The regional arithmetic was sound; my combined account was not

26

Data colleagues

Four leads within a 550-person industrial manufacturer

₹6.9 crore

Annual data-function expense

Separate from enterprise revenue and operating authority

32 years

Analytical career

Entry in July 1994; industrial employer since September 2007

A letter from Malini Zhevqemi

Dear reader,

Portrait of Malini Zhevqemi

A summary earns its place when the decision it supports remains faithful to the work underneath it. I have approved an average that gave two unequal populations equal weight. That error taught me to ask whose experience a number represents, what it leaves out and whether the person using it is being asked to decide something the evidence never measured.

I signed off the seventy per cent figure because the two regional percentages looked comparable. One region had ninety complete order-review records out of one hundred; the other had four hundred and fifty out of nine hundred. Averaging ninety and fifty gave seventy. Combining the underlying records gave five hundred and forty out of one thousand, or fifty-four per cent. The arithmetic in each region was sound. The way I allowed the regions to stand for the whole was not.

Malini Zhevqemi

Chief Data Officer
Strategic priorities

Where I focus my leadership.

Performance

What the priorities delivered.

Priority outcome 01

Correcting the combined rate I approved without weighting the records

In 2019 I approved a report that averaged two regional percentages into a combined 70% rate. The first region had ninety complete order-review records out of one hundred; the second had 450 out of 900. Both used the same completeness criterion. The pooled result was 540 complete records out of 1,000, or 54%. The original calculation gave the small regional population the same influence as the larger one. It could describe an unweighted average of two regional rates, but that was not the question the combined report claimed to answer. Management wanted the proportion of complete records across the reviewed population. I had allowed a convenient summary to change the unit being represented. Repairing the report cost ₹19 lakh. The correction from 70% to 54% was sixteen percentage points; it did not show that the underlying records had deteriorated between two dates. I retained that distinction so the correction itself would not create a second misleading account. The reviewed criterion concerned commercial-record completeness, not product safety or technical acceptance. I worked with the responsible business owners to restate the population and explain the correction. My approval remained part of the record. It would have been easy to describe the issue as a dashboard formula, but the leadership error was accepting the meaning attached to that formula without checking which unit the combined number represented. The outcome was a corrected account and a repair cost, not a measured improvement in operating performance. The case now informs how I examine summaries prepared for executive decisions. A rate should make its numerator, denominator and intended population clear enough that a reader can tell whether the question concerns regions, records or some other unit before using it to judge the enterprise.

Priority outcome 02

Keeping hinge wear among returns separate from a shipment failure rate

In 2022 a review of 180 returned totes found sixty-three with recorded hinge wear. The resulting 35% described the returned group. A draft interpretation was moving toward a claim that 35% of all shipped totes had that condition. I stopped the wider inference while keeping the finding available to technical and operating colleagues. The returns had entered the dataset through a particular process. They were not a random or complete account of all products in use. A separate count of 35,000 shipments did not create a suitable denominator either: it was not a matched cohort with comparable time in use and follow-up. Dividing sixty-three by that total would have produced another number without resolving the population problem. We funded ₹52 lakh of follow-up data work to make the next enquiry more useful. The programme concerned the connection between product records, exposure and observation. It did not establish a technical cause for the wear or certify the suitability of a tote for a particular use. Those responsibilities remained with qualified owners. My contribution was to distinguish an important signal from an estimate it could not support. The return finding deserved attention even though it did not describe every shipped unit. Rejecting the wider percentage was not a reason to dismiss the sixty-three observations, and retaining them was not permission to make the population claim. The reviewed outcome is a bounded finding and a funded next step. It contains no invented reduction in failures, safety incident or customer compensation. I use the case to show that data leadership should help colleagues ask the next answerable question. A limitation is most useful when it protects the current evidence and makes the additional work needed for a wider conclusion understandable.

Priority outcome 03

Showing the family forecast errors hidden by a correct total

A 2023 planning review compared two product families. Actual quantities were 1,200 and 800 units; their forecasts were 1,600 and 400. Both actual and forecast totals were 2,000. A summary based only on the net total error therefore looked exact, even though each family was wrong by 400 units in the opposite direction. The sum of absolute family errors was 800 units, or 40% of the 2,000 actual units on that defined quantity basis. That measure did not mean every forecast elsewhere in the company was 40% wrong. It showed why the correct total could not answer the mix question relevant to this reviewed planning decision. We approved a ₹73 lakh planning-measurement programme. My team worked with operating and commercial colleagues to make the level of the decision explicit. A total can be useful for one purpose while failing to distinguish the family quantities another purpose needs. The problem was not that totals should never be used; it was that the total's success was being allowed to stand for a more detailed result. I did not infer actual shortages, excess stock or financial loss from the example alone. Those consequences would require their own evidence about orders, inventory and operating choices. Nor did the new measurement programme establish that future forecasts would improve. It changed the account through which the reviewed forecast could be assessed. The case helped us discuss error without treating it as one universal score. A leader should understand which differences cancel when information is combined and whether those differences still matter to the decision. Here, opposite family errors disappeared from the total while remaining relevant to the work. Preserving them made the planning conversation more exact without manufacturing a completed business benefit.

Priority outcome 04

Holding a 99.2%-accurate model that missed all forty uncommon cases

A 2024 predeployment evaluation contained 5,000 orders, including forty identified by responsible reviewers as requiring special commercial documentation. The other 4,960 were routine. A candidate triage model labelled every order routine. Its overall accuracy was 99.2%, but it missed all forty cases the proposed assistance needed to distinguish. We held the model and incurred ₹44 lakh in assessment and rework. The evaluation occurred before deployment; this case claims no actual customer harm or missed legal obligation. The special-documentation labels concerned the defined commercial review, with responsible people retaining the decisions about actual orders and required records. The headline score was arithmetically correct. It was unhelpful for the intended task because routine cases dominated the reviewed population. A rule that never identified an uncommon case could appear highly accurate without providing the distinction the business wanted. I asked the team to show the different kinds of correct and incorrect decisions rather than defend the aggregate percentage. This was not an argument that accuracy has no use or that one replacement metric would settle every deployment question. The evaluation needed to reflect the intended decision, the relative consequences and the work available to human reviewers. A better score would still need examination in the context of the proposed assistance. The outcome was a held candidate and a cost, not a measured productivity gain. I retained the simple all-routine comparison because it made the issue understandable outside the modelling team. Data leadership should help an executive see why a number can be true and still fail to justify the action attached to it, especially when the work of interest is uncommon in the dataset.

Priority outcome 05

Measuring the complete job instead of adding two stage medians

In 2025 we examined forty matched pick-and-pack jobs. The picking-stage median was six minutes and the packing-stage median eight. Adding them gave fourteen minutes. The median of each same job's combined stage time was nineteen minutes. The stage summaries and the paired total answered different questions. The difference did not reveal five minutes of newly discovered waiting. The combined measure contained the two matched stage times, without adding a waiting interval. Medians select positions within distributions, and the observations at those positions need not belong to the same jobs. Adding separately ordered summaries did not reconstruct the distribution of complete-job times. We funded ₹28 lakh of measurement work to retain the pairing and explain the result to operating colleagues. The forty jobs were a defined reviewed sample. Their median did not establish a universal service promise, a future delivery commitment or a ranking of employees. Operations retained authority over the work itself. My contribution was to connect the measure with the question. Stage medians could still help describe each activity. A decision about the combined work needed the job-level relationship preserved. Neither summary had to be declared useless; the problem was treating their arithmetic combination as though it had measured the end-to-end quantity directly. The reviewed outcome was a clearer measurement account and programme funding, not an operating improvement or a newly diagnosed bottleneck. I use the case because the incorrect fourteen-minute figure was so easy to explain. A simple calculation can feel more convincing than the evidence it is supposed to summarise. The leader's task is to make the correct distinction equally understandable, so colleagues can choose a measure that fits their decision without inventing a cause for the difference.

Stakeholder voices

What those I have served alongside say.

Malini explained why a correct total forecast could still leave the family mix wrong. She kept the programme's cost separate from any claim of a benefit we had not yet measured.
Ishaan MezqaviCEO, Renvqathi Transit Containers; fictional colleague
She did not describe the gap between stage medians and matched-job time as a newly discovered delay. That let us discuss what the measurement actually showed before deciding whether the work needed to change.
Devika NevqurmiCOO, Renvqathi Transit Containers; fictional colleague

Outlook

Perspectives on what comes next.

An invitation

Contact

A first outside board opportunity where data judgement can complement the institution's operating and financial expertise. I hold 2% within employee ownership and have no statutory appointment. Fictional IICA registration is complete but assessment remains unfinished; twenty-four provisional days require review against the actual role and my executive commitments.

Open to
  • Board appointments
  • Advisory roles
  • Speaking invitations

office@malinizhevqemi.example