Prepared for boards, nomination committees & search advisers

File No. CDO-056

Portrait of Ruth Qelzavmi
Ruth Qelzavmi

Ruth Qelzavmi

A clear result should keep its meaning intact

SubjectRuth Qelzavmi
PositionChief Data Officer
BaseIndia
LanguagesEnglish, Mizo, Hindi
StatusI am exploring a first board contribution where data products shape commercial or operating decisions.

Summary

I grew up in Aizawl and completed a statistics degree at the fictional Qelvotri College of Statistics in May 1999. I began employment in July at Temqavri Statistical Services. The work taught me that a useful calculation needs an account of what was observed before it needs a polished display. I was interested in the small choices that could change the meaning of a result: which event had been recorded, which period it belonged to and what an empty field actually meant. Those questions were initially part of careful supporting work, not a mandate to make decisions for the client.

Keep the history that makes a result intelligible

In 2019 I approved an update that overwrote earlier versions of amended match results. The review covered 118 match records, seven of which had received authorised amendments. The current values could be correct while the service's account of what had changed was incomplete. We spent ₹41 lakh restoring the supported version histories. That repair did not make us the authority deciding the sporting result; it made our data service better able to explain the result supplied by the responsible source.

I am Ruth Qelzavmi, fictional chief data officer of Vezqatri Sports Data Services. I grew up in Aizawl and now work in Kohima. Our 188 colleagues supply regional indoor-sport feeds and archive analysis, with ₹79 crore FY2026 revenue. I lead thirty-six data colleagues through four leads, reporting to Simon, our CEO. Anita manages relationships with authorised competition sources. My work concerns the meaning and handling of the data, including where a neat figure might imply a conclusion the underlying record cannot support.

The cases move from result revisions to feed timing, unplayed fixtures, annotation review and comparisons across competition formats. Each required a different data decision. A timestamp difference was not automatically a measure of delivery speed. A fixture without play was not a played match with no performance. Two annotators agreeing did not establish that their description was correct. These are practical product questions with commercial consequences, because customers may rely on a compact display long after the conversation that produced it has been forgotten.

The latest result needed a recoverable path

Seven amended records retained their supported earlier versions and source changes; 111 records in the reviewed set were unchanged. The correction repaired our account without altering official competition decisions.

An apparent delay depended on the clocks used

Only 420 of 600 reviewed event pairs had a supported timing basis across two feeds. The remaining 180 belonged to a third feed with unresolved clock evidence, so the revised account did not invent a whole-service latency result.

Agreement could preserve the same mistake twice

Two annotators agreed on ninety-two of one hundred reviewed descriptions. Specialist examination found fourteen shared mistakes within that agreed group, showing why agreement could not simply be labelled accuracy.

Current focus

I am examining how archive users compare performance across competition editions with different formats. A convenient average may conceal a change in the opportunity to accumulate the underlying measure. The service should preserve the relevant competition context before a product asks readers to interpret a trend as improvement or decline.

Conversations I welcome

I am exploring a first board contribution where data products shape commercial or operating decisions. I have executive presentation experience and no statutory seat. My fictional proficiency assessment was completed in September 2026 after databank registration that April; twenty-three days remains a provisional estimate of annual outside capacity.

Exhibit ATrack record

ItemMeasureFigure
01Data careerStatistical-services support through CDO responsibility27 years
02FY2026 enterprise revenue₹48 crore live feeds; ₹31 crore archive analysis₹79 crore
03Enterprise employeesMarch 2026 headcount188
04Data colleaguesFour leads within the CDO function36

Exhibit BStatement of approach

Correcting a value should not erase the reason it changed. I once approved a sports-results update that replaced earlier entries without preserving their amendment history. The latest display looked cleaner, but the record could no longer explain what had been supplied before. I want data products to retain the distinction between a current result, its source history and the conclusions a user is entitled to draw from either.

Signed — Ruth Qelzavmi

Exhibit CSelected matters

Matter 01Ref. CDO-056-M01

Restoring the amendment history I had allowed an update to erase

In 2019 I approved a results-update approach that replaced an earlier value when an authorised source supplied an amendment. The current display looked simpler, and the delivery team could maintain one visible result for each match. In a review of 118 match records, seven had been amended. Our handling preserved the latest values but not a sufficient account of what had changed or what the service had supplied before. I had treated the latest result as though it were the whole record.

Anita challenged that approach when a customer asked why an archived extract differed from the current service. The product sponsor preferred to keep the single-result model and explain exceptions manually. That would have avoided a structural change, but depended on someone remembering the history outside the service. I recommended restoring the supported earlier versions and their source relationships. We spent ₹41 lakh on recovery, review and revised handling, accepting a delay in the archive update rather than presenting the cleaner display as sufficient evidence.

The reviewed set retained 111 unchanged records and seven with supported amendment histories. We did not invent versions where the available evidence could not establish them, and did not treat the data team as the body deciding the official result. Authorised competition sources remained responsible for their own decisions. Our task was to preserve the relationship between those instructions and the account we supplied. The repair did not demonstrate a change in sporting performance, an athlete's eligibility or a financial loss to a customer.

I accepted responsibility for the original approval. The trade-off was a more demanding record structure and the cost of correcting a simplification that had initially looked efficient. I would now ask what a user needs to understand after a material change, not only what they need to see at the moment of viewing. A current value can be correct while its history is inadequate. The service became more useful because a reader could follow a supported amendment without relying on an undocumented explanation from a colleague who happened to remember it.

Matter 02Ref. CDO-056-M02

Withdrawing a latency comparison that the clock evidence could not support

A 2022 review assembled 600 event pairs from three sports-data feeds. A preliminary account reported an apparent median delay of 4.8 seconds by subtracting source timestamps from receipt timestamps. The number looked like a direct measure of delivery speed. Technical colleagues questioned whether the clocks, timestamp meanings and matching events supported that subtraction across all three feeds. The arithmetic could be performed, but that did not establish a common measurement basis.

The service sponsor wanted to use the figure immediately to demonstrate the need for faster infrastructure. I agreed that delivery performance mattered, but the proposed claim could send the enterprise toward an intervention without first establishing what the number measured. We spent ₹53 lakh on the timing review and diagnostic work. The data team examined event matching and timestamp interpretation with the responsible technical colleagues; it did not assume that a familiar date-time field carried identical meaning in every source.

For 420 event pairs across two feeds, the review established a supported timing basis. Their median was 2.3 seconds. The remaining 180 pairs came from the third feed, where the clock evidence remained unresolved. I published the bounded account and withheld a whole-service latency claim. The 2.3-second figure was not described as an improvement from 4.8 seconds: the earlier figure was inadequately founded, and the revised population differed. We had improved the validity of an account, not demonstrated that the delivery system had become faster.

The consequence was losing a simple comparison that the sponsor had hoped to use in an infrastructure proposal. The third feed remained a question for further work rather than a set of outliers to remove without explanation. I learned to agree the event and timing basis before asking a subtraction to carry an operational conclusion. A measurement can become more defensible while the underlying service remains unchanged. Keeping that distinction visible allowed the next technical decision to address the actual evidence instead of treating a revised statistic as a performance achievement.

Matter 03Ref. CDO-056-M03

Keeping unplayed fixtures out of a sporting-performance average

In 2023 an archive product prepared a view of forty-eight scheduled fixtures. Thirty-nine had been played, five were recorded by the competition source as walkovers and four had been cancelled. A completion rule would have supplied numerical zero values where the service lacked played-match observations, allowing one performance calculation to run across the whole schedule. The resulting table would have looked complete while implying that an unplayed fixture supplied the same kind of evidence as a played match.

The product sponsor argued that customers expected a full schedule and a simple average. Anita pointed out that the administrative status and the observed sporting activity answered different questions. I supported a ₹36 lakh model revision that retained the forty-eight-fixture account while distinguishing the thirty-nine played matches from the other nine. The source's walkover and cancellation instructions remained visible. The data team did not invent play, reinterpret the competition's administrative outcome or assign a generic sporting score to make the calculation easier.

Product colleagues had to present the schedule and performance views with their respective populations. A customer could still see all forty-eight fixtures, but a calculation based on played-match observations could not silently treat the nine unplayed fixtures as performances containing zeros. We retained the reason for exclusion alongside the view, rather than deleting the records from the archive. Where a different competition-specific calculation was required, it needed its own supported definition and source authority instead of inheriting the default performance treatment.

The trade-off was a less uniform product and more explanation for users who wanted one convenient number. We did not claim that the change improved an athlete's ranking or corrected official competition standings. It corrected the account our service was prepared to make from the supplied observations. I would now ask whether a missing numerical value means no activity, an unobserved activity or an administrative state before selecting a default. The fixture exists in the schedule even when the sporting performance does not. A model that preserves both facts is more useful than a complete-looking table that makes one disappear inside the other.

Matter 04Ref. CDO-056-M04

Finding shared mistakes inside a high annotation-agreement figure

In 2024 two annotators independently described one hundred selected sporting sequences. They agreed on ninety-two descriptions. A project account proposed calling that ninety-two-percent accuracy, which would have made the process appear ready for a broader release. A domain specialist challenged the label: agreement showed that the annotators had used the same description, but did not establish that the description was correct. The two people could apply the same ambiguous instruction and reproduce the same error.

The delivery sponsor favoured proceeding with the agreement figure and reviewing the eight disagreements later. I asked for specialist examination of the agreed group as well. That review found fourteen shared mistakes among the ninety-two agreed descriptions. The apparent consistency had concealed a material problem in the interpretation being used. I withdrew the accuracy claim and supported ₹49 lakh of work on definitions, source review and revised evaluation, accepting a slower release discussion rather than treating agreement as a completed quality assessment.

The work distinguished the agreement measure from the evidence needed to assess correctness. We retained the original one-hundred-sequence review and the specialist findings, including where both annotators had made the same mistake. We did not derive a new whole-service accuracy percentage from this selected set or assume that the remaining descriptions represented every type of sporting sequence. Domain practitioners helped clarify the instructions and identify examples that exposed ambiguity. Product and delivery colleagues then had a more specific account of what needed further evaluation.

The consequence was losing a favourable headline and paying for work that a superficial reading of the agreement figure might have postponed. I would now ask what a review method can establish before deciding how to name its output. Consistency is useful evidence, but it is not the same as truth. A data leader needs to make room for the practitioner who can explain why two identical answers are both wrong, especially when a convenient percentage has already become part of the release story.

Matter 05Ref. CDO-056-M05

Refusing to smooth a performance series across changed competition formats

In 2025 an archive-analysis request compared performance measures across twenty-four competition editions. Seventeen used a consistent format within their relevant comparison groups, while seven had changed material playing or progression conditions. The proposed chart would have treated every edition as directly comparable after a simple numerical adjustment. That produced a smooth series, but the adjustment had not established that participants had the same opportunity to accumulate the measure in each format.

The analytics sponsor wanted a continuous trend that customers could read without studying competition details. I understood the value of continuity, but Anita and the domain analysts could explain differences that the proposed normalisation did not resolve. We spent ₹38 lakh on the archive model and source review. The revised representation retained edition, stage and the relevant format context, with comparisons limited to groups whose basis could be explained. The seven changed editions were not deleted or described as defective data; they remained available with the conditions that mattered to interpretation.

I declined to label the adjusted series as evidence that performance had improved or declined across the whole set. The data function had not established that conclusion, and an attractive chart could not supply the missing comparability. Where users wanted a broader analytical model, it required an explicit method and examination by the appropriate specialists. We did not assume a universal conversion between formats or create fictional observations for the activity that a different format might have allowed. The archive preserved what happened rather than rewriting it to fit a preferred trend.

The trade-off was a less seamless product and a narrower immediate claim. Customers could still study the editions, but the service asked them to consider context that the original chart would have hidden. I would now agree what makes two observations comparable before designing the series that joins them. Historical data can be accurate at the record level and still support a misleading comparison when its conditions are removed. The improvement was a more faithful analytical starting point, not a measured change in the athletes or competitions represented by the invented example.
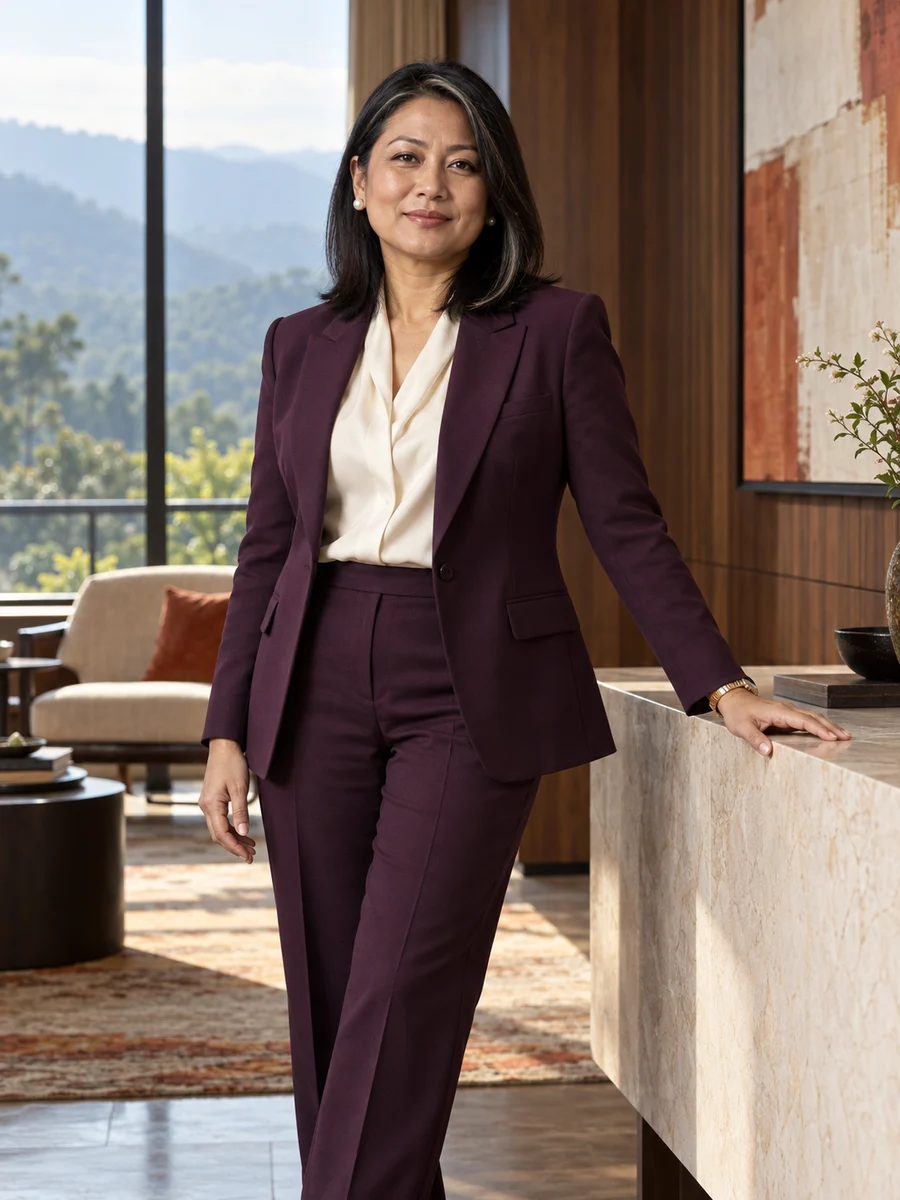
Exhibit DFormation

  • Bachelor of Science in StatisticsQelvotri College of Statistics1999

Exhibit EReferences

In this fictional timing review, Ruth did not convert a lower subset median into a claim of faster delivery. She retained the unresolved third feed and explained what the ₹53 lakh work had established, even though that made the management account less immediately favourable.
Simon QervazliFictional CEO, Vezqatri Sports Data Services
The invented amendment repair kept our source relationships distinct from the service's handling. Ruth accepted her original approval and supported a record that could explain the seven changes without making our data team the authority deciding the sporting result.
Anita TevqozriFictional competition liaison, Vezqatri Sports Data Services

Exhibit FPublished views

CorrespondenceNext steps

An invitation

Contact

I am exploring a first board contribution where data products shape commercial or operating decisions. I have executive presentation experience and no statutory seat. My fictional proficiency assessment was completed in September 2026 after databank registration that April; twenty-three days remains a provisional estimate of annual outside capacity.

Open to
  • Board appointments
  • Advisory roles
  • Speaking invitations

office@ruthqelzavmi.example